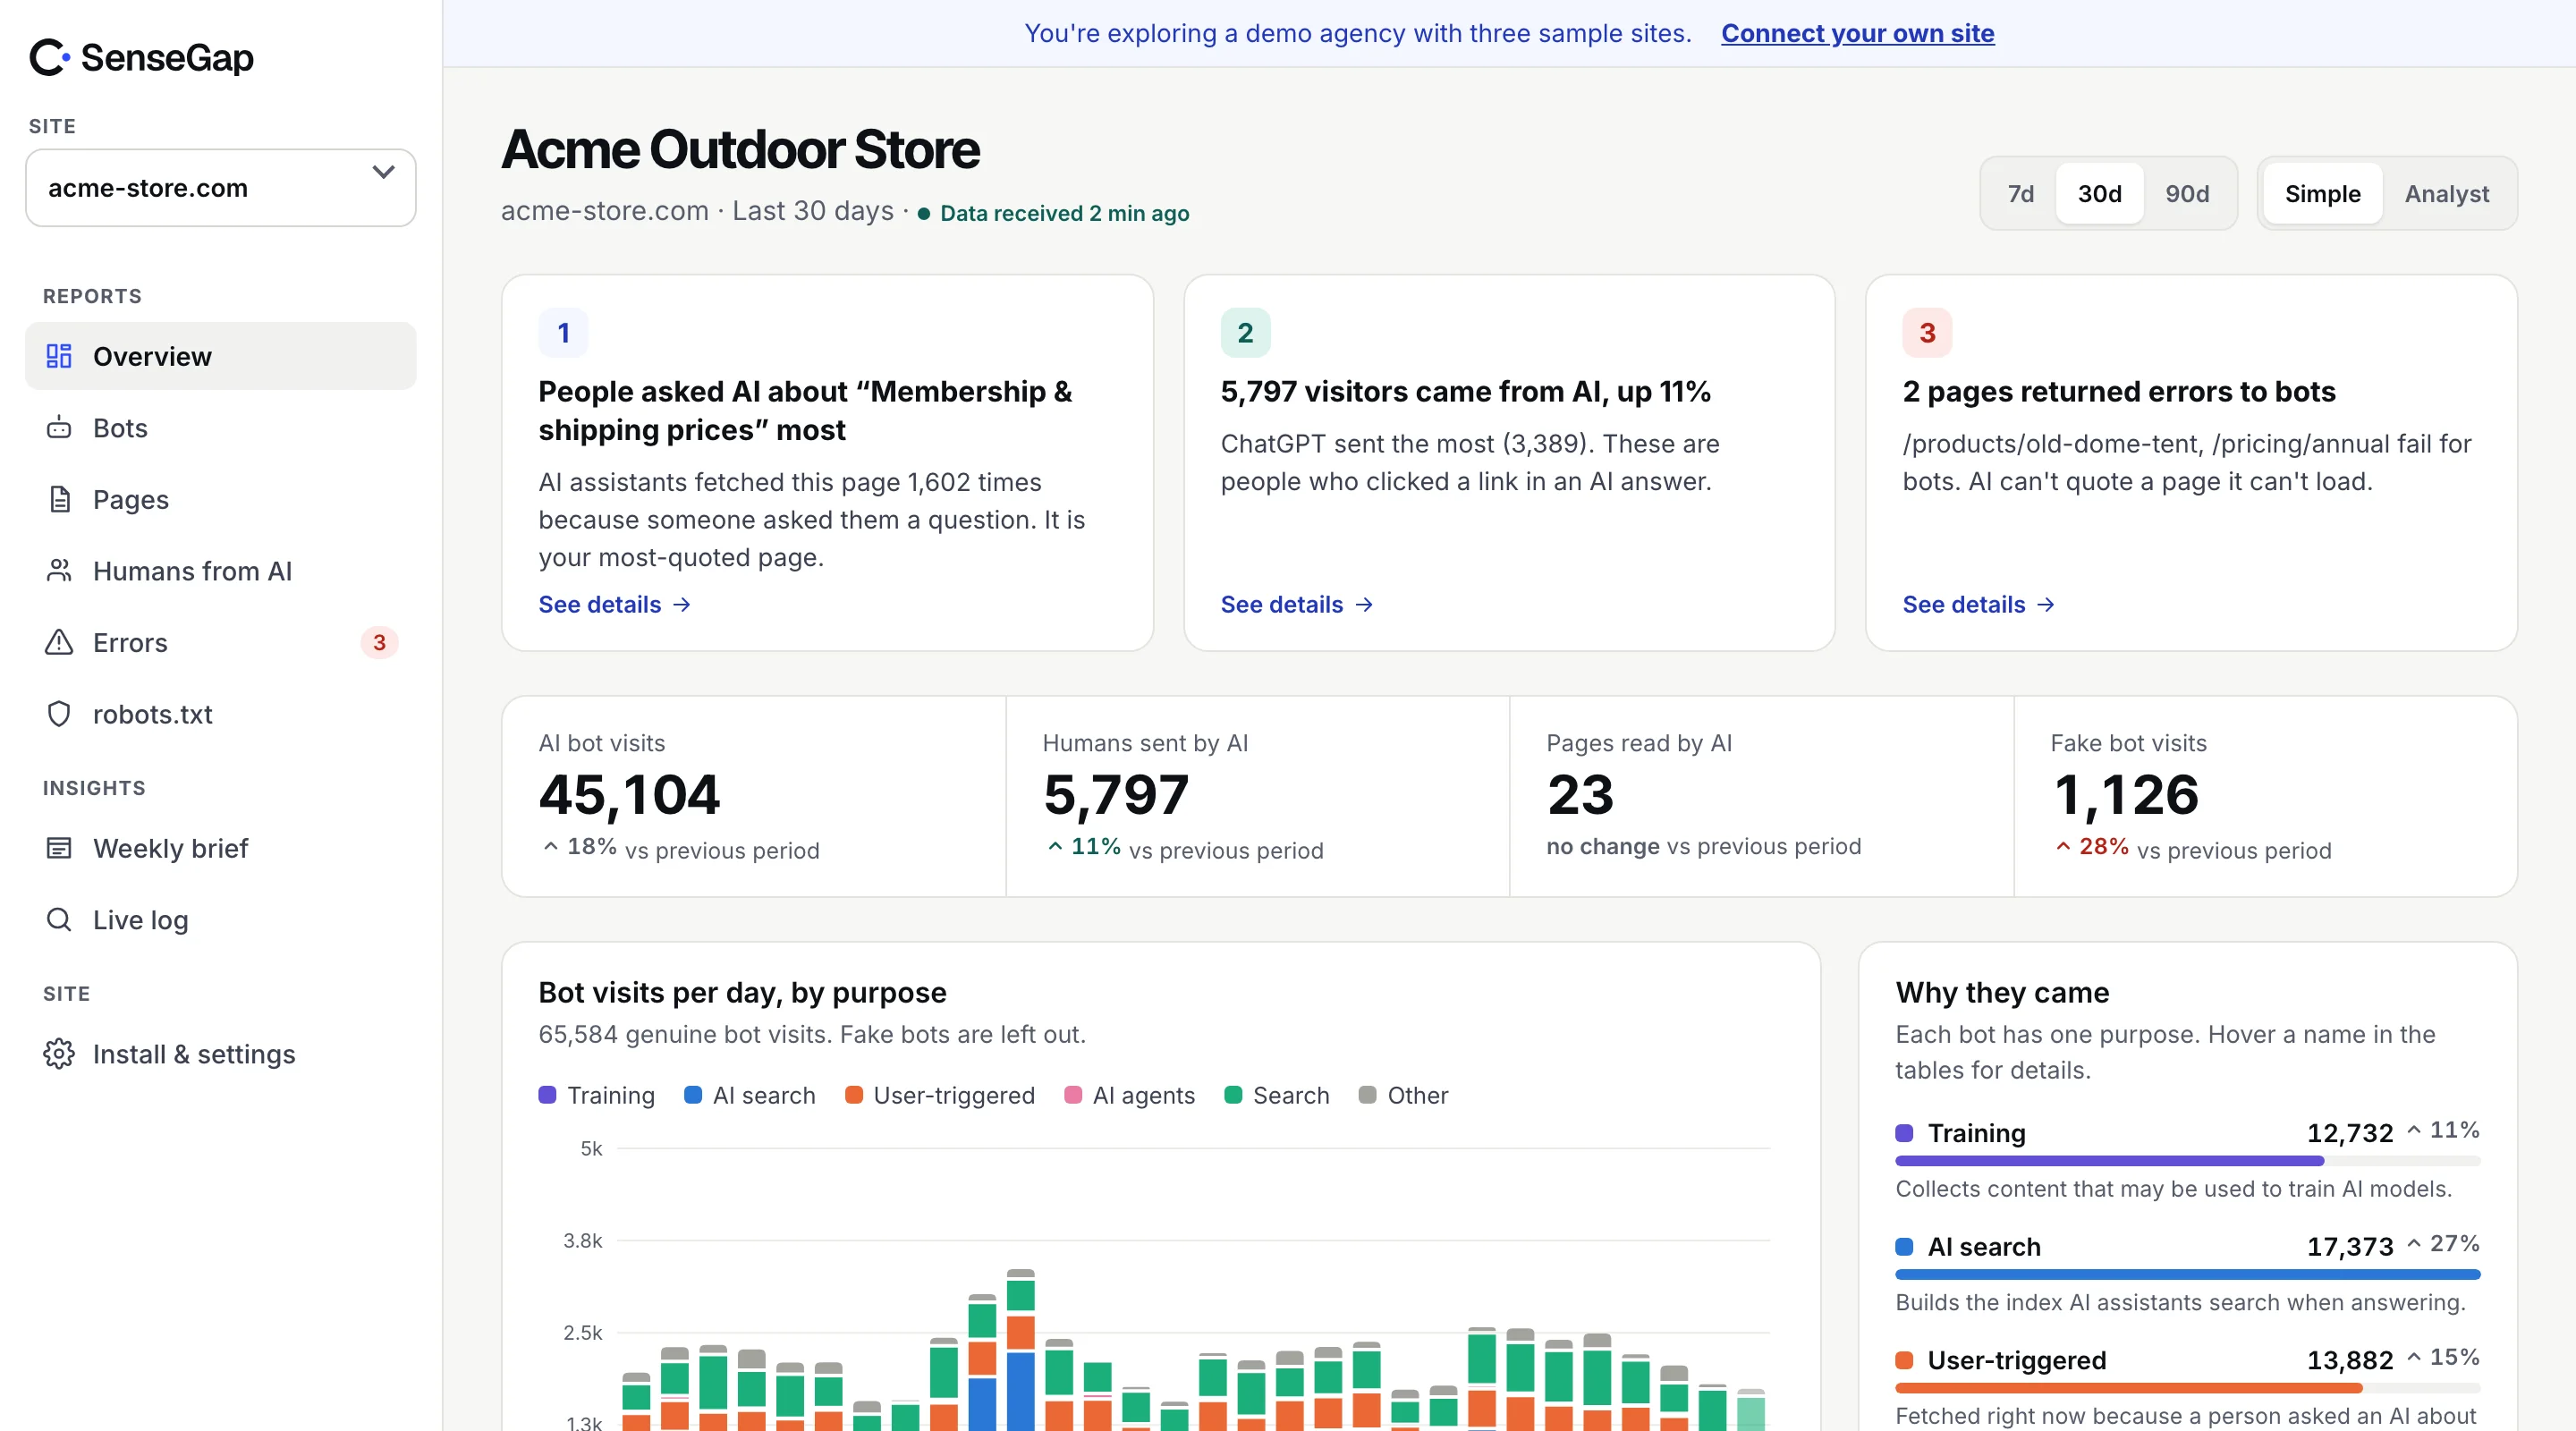
 See it on a real storeBots, pages and people sent by AI on an example store. No sign-up.
Search engines, run by Google.
What is Storebot-Google? Google's search engine crawler. Verifiable by IP ranges and reverse DNS.
Run by Google.
Purpose: Search engines. A visit means your page is being crawled for a classic search index.
robots.txt name: Storebot-Google.
Verifiable by IP ranges and reverse DNS.
At a glance, the facts in one table.
Storebot-Google at a glance. Taken from SenseGap's open bot directory, the same data that sorts every visit in the dashboard.
All bots| Storebot-Google | |
|---|---|
| Operator | |
| Purpose | Search engines |
| User agent contains | Storebot-Google |
| robots.txt name | Storebot-Google |
| Verification | IP ranges + Reverse DNS |
| Documentation | None listed |
Purpose, what it does and why it came.
What Storebot-Google does. SenseGap sorts every visit by purpose. Storebot-Google is in the Search engines group.
Storebot-Google is Google's search engine crawler that indexes pages for Google's search results.
What a visit means
A visit means your page is being crawled for a classic search index. SenseGap keeps search engines in your reports so you can compare AI activity with them.
Comparing how often a search engine and AI assistants read the same pages shows which content AI relies on more, or less, than search does.
Detection, the header SenseGap matches.
How SenseGap recognizes Storebot-Google. By its User-Agent header. A separate check then decides whether the visit is real.
Every request carries a User-Agent header naming the software that sent it. SenseGap counts a request as Storebot-Google when that header contains Storebot-Google, in any letter case. The header is plain text, so any script can copy it. Matching the name is where recognition starts, not where trust starts.
/Storebot-Google/iVerification, how to tell a real visit from a fake.
How to verify Storebot-Google. Google publishes its IP ranges and DNS names, so a real visit can be proven.
How we verify botsgooglebot.json
Published by Google at developers.google.com. A real Storebot-Google visit comes from an address in this list.
Open the listChecked on every visit
SenseGap runs both checks on every visit that claims to be Storebot-Google, IP ranges first, then reverse DNS confirmed by a forward lookup. A pass is marked Real. A visit that sends the name and fails is marked Fake, and stays out of your other reports.
- 01
Look up the visiting address
Run a reverse DNS lookup on the IP address the request came from. It returns a hostname.
- 02
Check the hostname
The hostname must end in .googlebot.com, .google.com or .googleusercontent.com. Anything else is not Storebot-Google.
*.googlebot.com *.google.com *.googleusercontent.com - 03
Look the hostname up again
Run a forward lookup on that hostname. It must return the same IP address, otherwise the reverse record could have been set by anyone.
$ host <visiting-ip>
… domain name pointer <hostname>.googlebot.com.

$ host <hostname>.googlebot.com
<hostname>.googlebot.com has address <visiting-ip>
robots.txt, rules you can copy.
Block or allow Storebot-Google in robots.txt. Its robots.txt name is Storebot-Google. Paste a group into the robots.txt at your site's root.
User-agent: Storebot-Google
Disallow: /User-agent: Storebot-Google
Allow: /User-agent: Storebot-Google
Disallow: /private/One rule catches people out. Under the robots.txt standard (RFC 9309), a crawler that finds a group naming it follows only that group and ignores your User-agent: * rules. If you add a Storebot-Google group, repeat in it anything from the catch-all group you still want applied.
robots.txt is a request, not a lock. To enforce a block, match the User-Agent header at your server or CDN. In nginx:
# nginx, inside a server block
if ($http_user_agent ~* "Storebot-Google") {
    return 403;
}
SenseGap reads your robots.txt and shows, bot by bot, what you allow and which bots fetched pages you disallowed. See what you get.
Trade-off, what blocking changes.
Should you block Storebot-Google? It depends on what you want from Google. Here is what each choice means.
If you allow it
Your pages can rank and be found in that search engine.
If you block it
Your pages drop out of that search engine's results over time. For major engines this is rarely what a site wants.
Google, every bot it runs.
More bots from Google. Google runs 8 bots in the directory, each with its own job.
- Google-NotebookLMAnswering a person · IP ranges + Reverse DNS
- Google-CloudVertexBotAI search index · IP ranges + Reverse DNS
- Google-InspectionToolSEO tools · IP ranges + Reverse DNS
- GoogleOtherOther · IP ranges + Reverse DNS
- AdsBot-GoogleOther · IP ranges + Reverse DNS
- Google user-triggered fetcherOther · IP ranges + Reverse DNS
- GooglebotSearch engines · IP ranges + Reverse DNS
Search engines, other bots with the same job.
Other search engine crawlers. Same purpose, different companies.
Browse the directoryFAQ, Storebot-Google in short answers.
Storebot-Google, answered plainly
What is Storebot-Google?
Storebot-Google is Google's search engine crawler that indexes pages for Google's search results.
Who runs Storebot-Google?
Google. SenseGap's directory has no documentation link for it yet.
What does a visit from Storebot-Google mean?
A visit means your page is being crawled for a classic search index. SenseGap keeps search engines in your reports so you can compare AI activity with them.
What user agent does Storebot-Google use?
Its User-Agent header contains "Storebot-Google". SenseGap matches it regardless of letter case.
How do I block Storebot-Google?
Add "User-agent: Storebot-Google" followed by "Disallow: /" to your robots.txt. robots.txt is a request, not a lock; to enforce it, block the user agent at your server or CDN.
How do I know a visit is really Storebot-Google?
Google publishes the IP ranges Storebot-Google uses (googlebot.json), so check that the visiting address falls inside one of them. You can also run a reverse DNS lookup on the address: the hostname must end in .googlebot.com, .google.com or .googleusercontent.com, and a forward lookup of that hostname must return the same address. SenseGap runs these checks on every visit.
Does Google publish IP ranges for Storebot-Google?
Yes, at https://developers.google.com/static/search/apis/ipranges/googlebot.json.
What happens if I block Storebot-Google?
Your pages drop out of that search engine's results over time. For major engines this is rarely what a site wants.