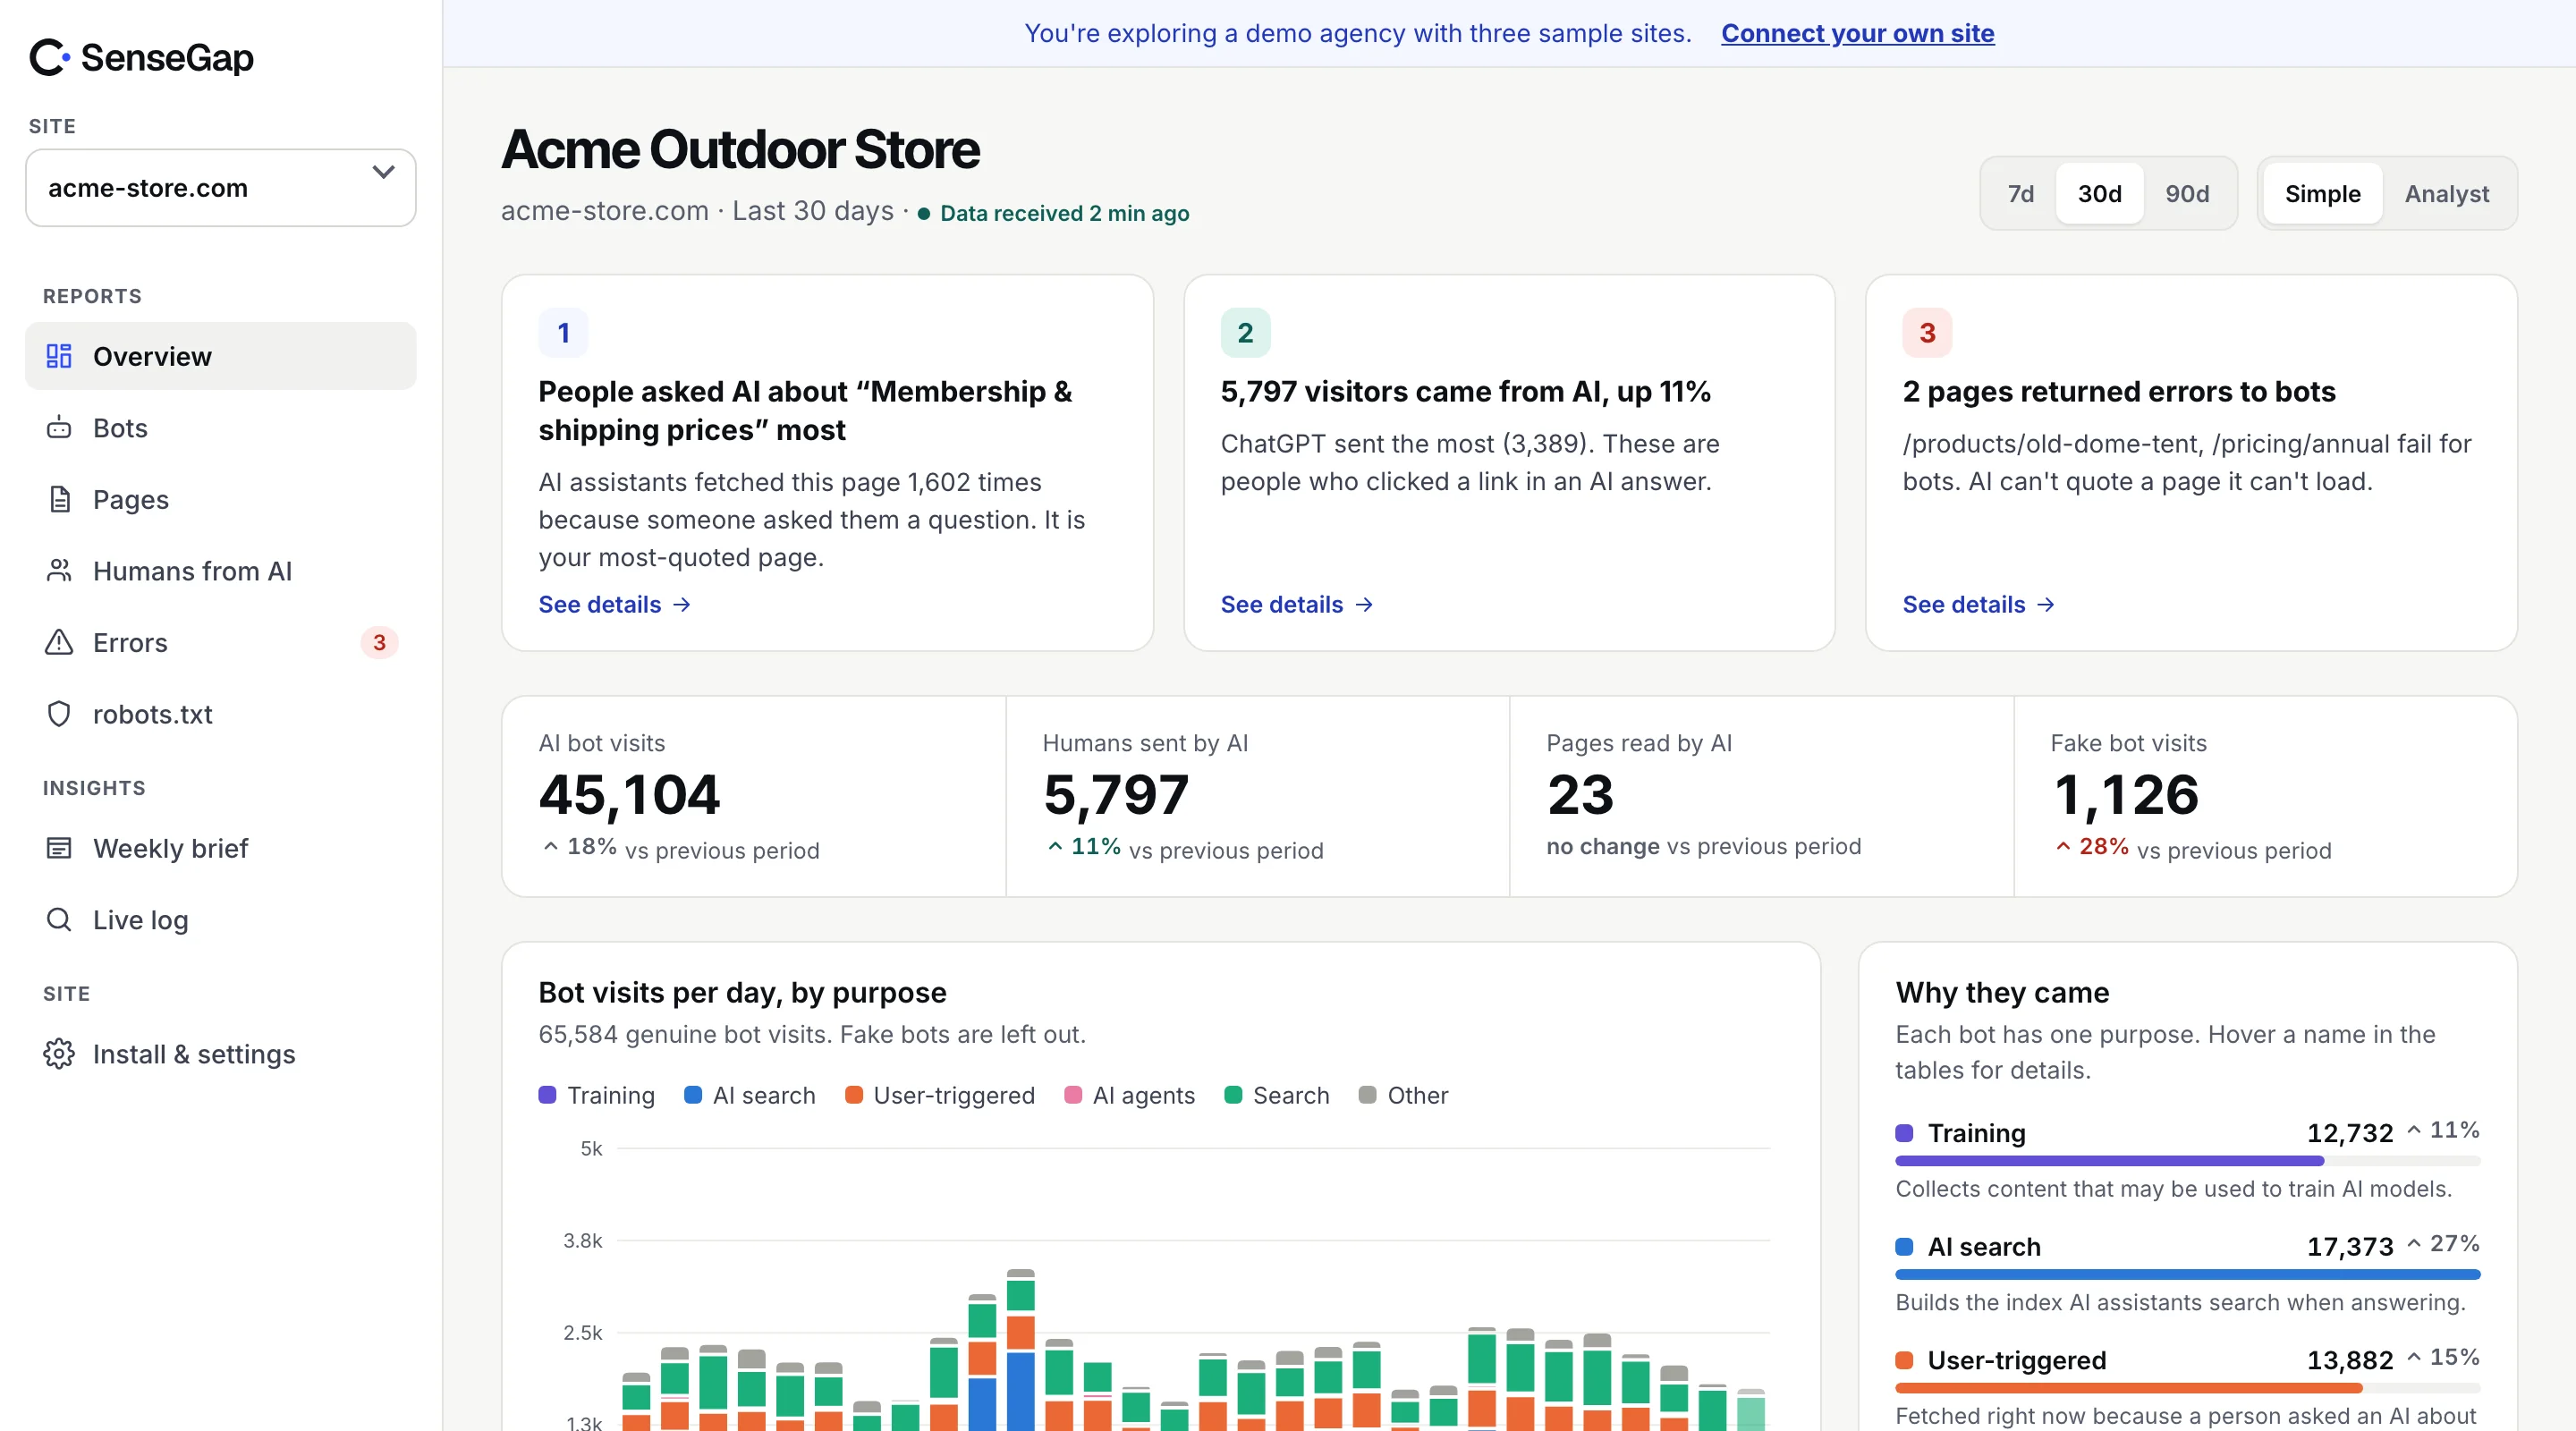
 See it on a real storeBots, pages and people sent by AI on an example store. No sign-up.
AI training, run by OpenAI.
What is GPTBot? OpenAI's crawler that collects AI training data. Verifiable by IP ranges.
Run by OpenAI, which documents it.
Purpose: AI training. A visit means your content is being collected, possibly for training.
robots.txt name: GPTBot.
Verifiable by IP ranges.
At a glance, the facts in one table.
GPTBot at a glance. Taken from SenseGap's open bot directory, the same data that sorts every visit in the dashboard.
All bots| GPTBot | |
|---|---|
| Operator | OpenAI |
| Purpose | AI training |
| User agent contains | GPTBot |
| robots.txt name | GPTBot |
| Verification | IP ranges |
| Documentation | platform.openai.com |
Purpose, what it does and why it came.
What GPTBot does. SenseGap sorts every visit by purpose. GPTBot is in the AI training group.
GPTBot is OpenAI's crawler that collects web content that may be used to train AI models.
What a visit means
A visit means your content is being collected, possibly for training. Nobody asked about you; training crawlers read the web in bulk and don't link back.
Training crawls say nothing about what people ask right now. SenseGap keeps them apart from visits made while answering a person, so a crawl spike never looks like demand.
Detection, the header SenseGap matches.
How SenseGap recognizes GPTBot. By its User-Agent header. A separate check then decides whether the visit is real.
Every request carries a User-Agent header naming the software that sent it. SenseGap counts a request as GPTBot when that header contains GPTBot, in any letter case. The header is plain text, so any script can copy it. Matching the name is where recognition starts, not where trust starts.
/GPTBot/iVerification, how to tell a real visit from a fake.
How to verify GPTBot. OpenAI publishes its IP ranges, so a real visit can be proven.
How we verify botsgptbot.json
Published by OpenAI at openai.com. A real GPTBot visit comes from an address in this list.
Open the listChecked on every visit
SenseGap runs this check on every visit that claims to be GPTBot. A pass is marked Real. A visit that sends the name and fails is marked Fake, and stays out of your other reports.
robots.txt, rules you can copy.
Block or allow GPTBot in robots.txt. Its robots.txt name is GPTBot. Paste a group into the robots.txt at your site's root.
User-agent: GPTBot
Disallow: /User-agent: GPTBot
Allow: /User-agent: GPTBot
Disallow: /private/One rule catches people out. Under the robots.txt standard (RFC 9309), a crawler that finds a group naming it follows only that group and ignores your User-agent: * rules. If you add a GPTBot group, repeat in it anything from the catch-all group you still want applied.
robots.txt is a request, not a lock. To enforce a block, match the User-Agent header at your server or CDN. In nginx:
# nginx, inside a server block
if ($http_user_agent ~* "GPTBot") {
    return 403;
}
SenseGap reads your robots.txt and shows, bot by bot, what you allow and which bots fetched pages you disallowed. See what you get.
Trade-off, what blocking changes.
Should you block GPTBot? It depends on what you want from OpenAI. Here is what each choice means.
If you allow it
Future models may learn from your content, so they know your products, prices and wording.
If you block it
New content stops reaching that company's training data. It doesn't remove what was already collected, and because training crawlers don't send visitors, it costs no clicks directly. OpenAI treats a Disallow for GPTBot as a signal that your content should not be used in training, and it is separate from OAI-SearchBot, so ChatGPT search can still show your pages.
OpenAI, every bot it runs.
More bots from OpenAI. OpenAI runs 4 bots in the directory, each with its own job.
AI training, other bots with the same job.
Other AI training crawlers. Same purpose, different companies.
Browse the directoryFAQ, GPTBot in short answers.
GPTBot, answered plainly
What is GPTBot?
GPTBot is OpenAI's crawler that collects web content that may be used to train AI models.
Who runs GPTBot?
OpenAI. OpenAI documents it at https://platform.openai.com/docs/bots.
What does a visit from GPTBot mean?
A visit means your content is being collected, possibly for training. Nobody asked about you; training crawlers read the web in bulk and don't link back.
What user agent does GPTBot use?
Its User-Agent header contains "GPTBot". SenseGap matches it regardless of letter case.
How do I block GPTBot?
Add "User-agent: GPTBot" followed by "Disallow: /" to your robots.txt. robots.txt is a request, not a lock; to enforce it, block the user agent at your server or CDN.
How do I know a visit is really GPTBot?
OpenAI publishes the IP ranges GPTBot uses (gptbot.json), so check that the visiting address falls inside one of them. SenseGap runs these checks on every visit.
Does OpenAI publish IP ranges for GPTBot?
Yes, at https://openai.com/gptbot.json.
What happens if I block GPTBot?
New content stops reaching that company's training data. It doesn't remove what was already collected, and because training crawlers don't send visitors, it costs no clicks directly. OpenAI treats a Disallow for GPTBot as a signal that your content should not be used in training, and it is separate from OAI-SearchBot, so ChatGPT search can still show your pages.